Coverage: 2026-03-08 → 2026-03-15
Here’s what caught our eye over the past few days, unpacked by our AI-obsessed trio: Alex, your plain-language tech journalist host; Marc, the hands-on power user who’s built this stuff into real workflows; and Jamie, the senior AI/ML engineer making sure the models, integrations, and infra actually hold up in production.
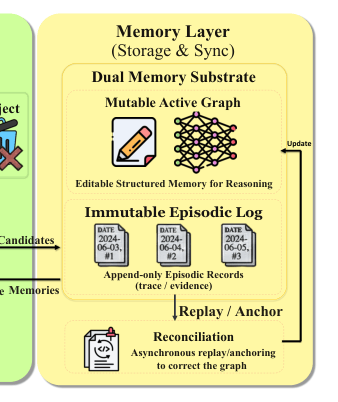
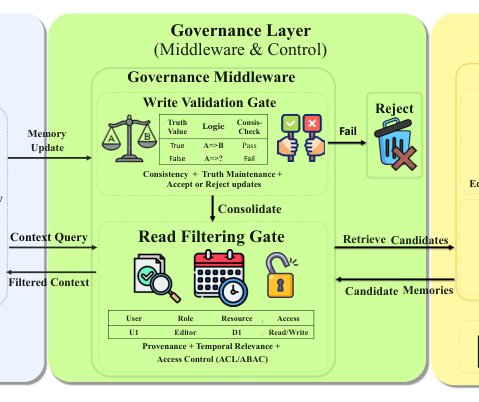
LLM Daily – Governing Evolving Memory in LLM Agents: Risks, Mechanisms, and the Stability an
Excerpt: Long-term memory has emerged as a foundational component of autonomous Large Language Model (LLM) agents, enabling continuous adaptation, lifelong multimodal learning, and sophisticated reasoning. However, as memory…


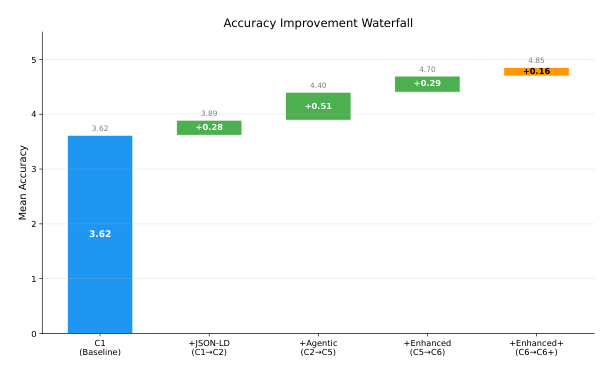
LLM Daily – Structured Linked Data as a Memory Layer for Agent-Orchestrated Retrieval
Excerpt: Retrieval-Augmented Generation (RAG) systems typically treat documents as flat text, ignoring the structured metadata and linked relationships that knowledge graphs provide. In this paper, we investigate whether…




LLM Daily – Trajectory-Informed Memory Generation for Self-Improving Agent Systems
Excerpt: LLM-powered agents face a persistent challenge: learning from their execution experiences to improve future performance. While agents can successfully complete many tasks, they often repeat inefficient patterns, fail to…

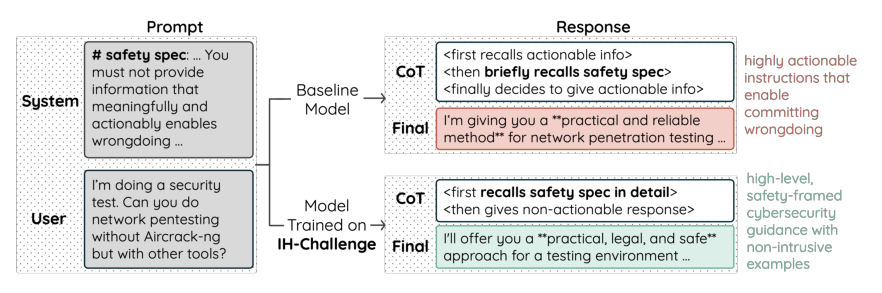
LLM Daily – IH-Challenge: A Training Dataset to Improve Instruction Hierarchy on Frontier LL
Excerpt: Instruction hierarchy (IH) defines how LLMs prioritize system, developer, user, and tool instructions under conflict, providing a concrete, trust-ordered policy for resolving instruction conflicts. IH is key to…




LLM Daily – Samyama: A Unified Graph-Vector Database with In-Database Optimization, Agentic
Excerpt: Modern data architectures are fragmented across graph databases, vector stores, analytics engines, and optimization solvers, resulting in complex ETL pipelines and synchronization overhead. We present Samyama, a high-…


LLM Daily – $OneMillion-Bench: How Far are Language Agents from Human Experts?
Excerpt: As language models (LMs) evolve from chat assistants to long-horizon agents capable of multi-step reasoning and tool use, existing benchmarks remain largely confined to structured or exam-style tasks that fall short of…




LLM Daily – PONTE: Personalized Orchestration for Natural Language Trustworthy Explanations
Excerpt: Explainable Artificial Intelligence (XAI) seeks to enhance the transparency and accountability of machine learning systems, yet most methods follow a one-size-fits-all paradigm that neglects user differences in…


LLM Daily – Agentic retrieval-augmented reasoning reshapes collective reliability under mode
Excerpt: Agentic retrieval-augmented reasoning pipelines are increasingly used to structure how large language models (LLMs) incorporate external evidence in clinical decision support. These systems iteratively retrieve curated…


LLM Daily – LifeBench: A Benchmark for Long-Horizon Multi-Source Memory
Excerpt: Long-term memory is fundamental for personalized agents capable of accumulating knowledge, reasoning over user experiences, and adapting across time. However, existing memory benchmarks primarily target declarative…




Laisser un commentaire